Telco Customer Churn — ANN
Executive Summary
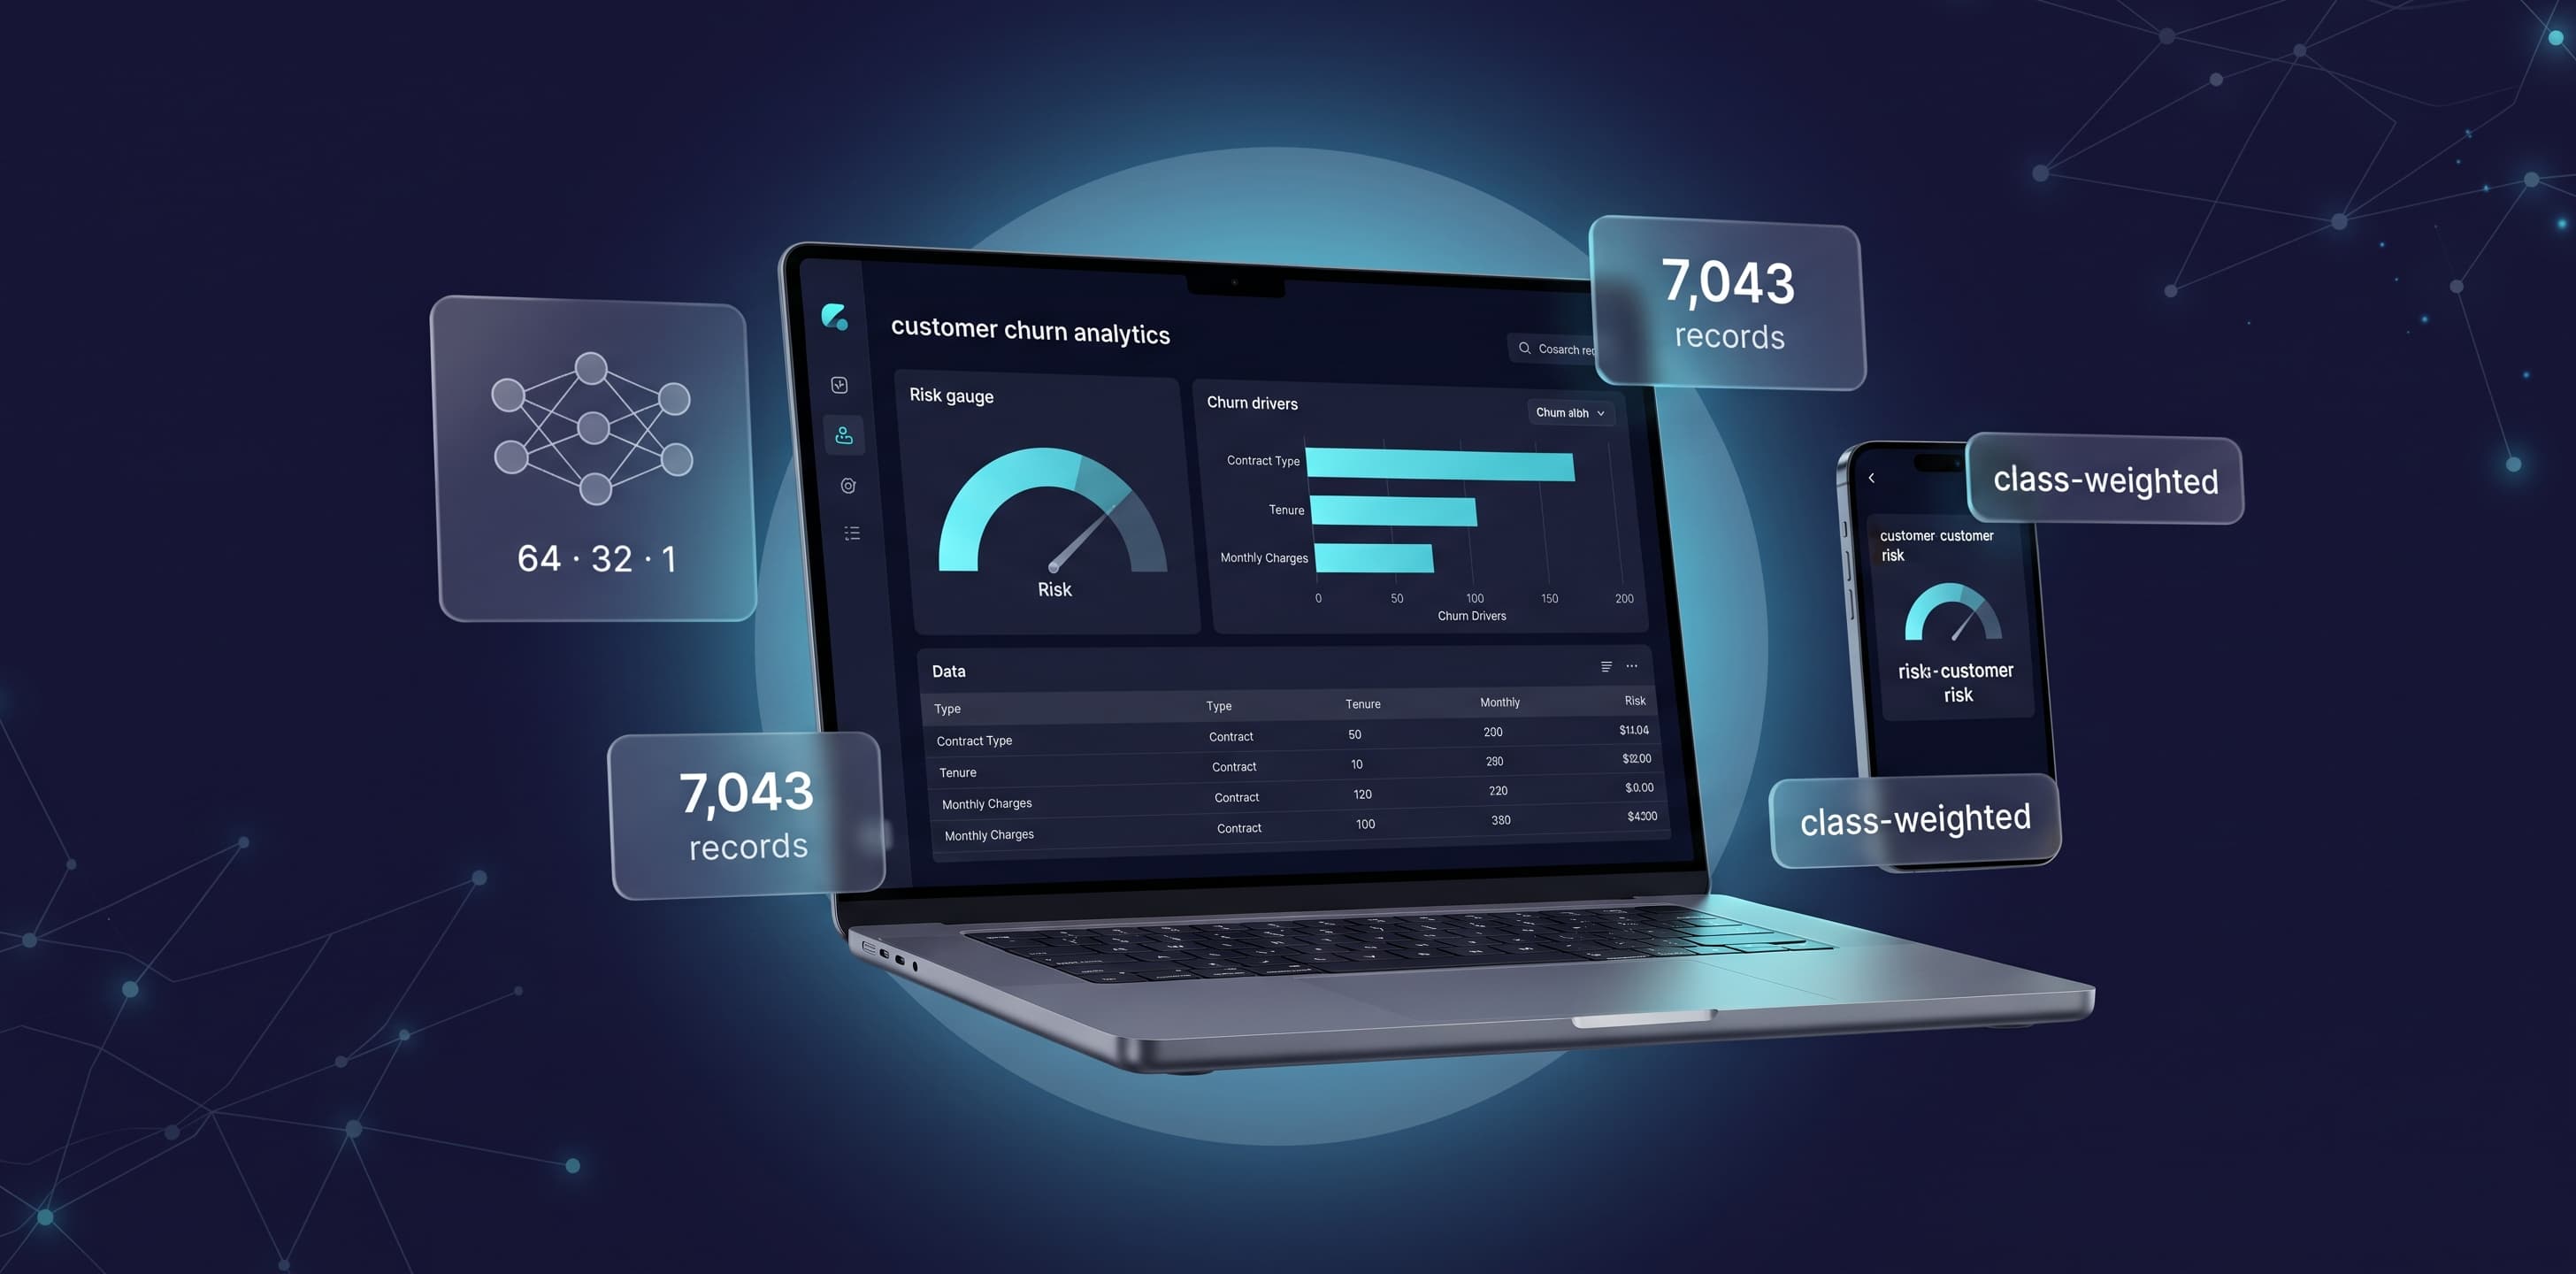
A Keras artificial neural network (64->32->1) that predicts customer churn on the 7,043-record IBM Telco dataset, paired with a Streamlit dashboard for individual and batch risk scoring.
Technical Context
The Build Logic
Executive Summary
An end-to-end deep-learning pipeline that predicts telecom customer churn from the IBM Telco dataset (7,043 records, 20 features). A compact Keras ANN (64 -> 32 -> 1) is trained with a stratified split and inverse-frequency class weighting to counter the imbalanced churn base rate, then served through a multi-page Streamlit analytics dashboard.
The Problem
Churn datasets are heavily imbalanced — most customers do not churn — so a naive model learns to predict "stay" and misses the customers who actually leave. Retention teams also need per-customer risk, not just an aggregate score, to prioritise outreach.
The Solution
- A feed-forward Keras ANN with a 64 -> 32 -> 1 architecture and dropout for regularisation.
- Inverse-frequency class weighting so the minority (churn) class contributes proportionally to the loss.
- A stratified train/validation/test split that preserves the churn ratio across every fold.
- A Streamlit dashboard for real-time individual risk assessment and batch CSV scoring.
System Architecture
-
Data Layer
Cleansing and encoding of the 20 raw Telco features (categorical one-hot, numeric scaling). -
Modeling Layer
A Keras Sequential ANN (64 -> 32 -> 1, sigmoid output) trained with class weights and early stopping on validation loss. -
Delivery Layer
A multi-page Streamlit app with single-record and batch scoring modes that surfaces the main retention drivers behind each prediction.
Engineering Decisions
Why Class Weighting?
Inverse-frequency weighting keeps the imbalanced churn class influential during training without discarding majority-class data through undersampling.
Why an ANN over a Tree Ensemble?
To practise deep-learning workflow design on tabular data — architecture, regularisation, and weighted loss — while keeping the model compact and fast to serve.
Pipeline Details
Dataset: 7,043 records, 20 features (IBM Telco).
Architecture: 64 -> 32 -> 1 feed-forward network.
Split: stratified train/validation/test preserving the churn ratio.
Serving: multi-page Streamlit dashboard (individual + batch scoring).
Outcome
A clean, reproducible churn-prediction pipeline that demonstrates imbalanced-data handling, ANN design, and practical model serving for a retention use case.
Scalability is the only standard
Ready to integrate these levels of intelligence and performance into your own ecosystem?